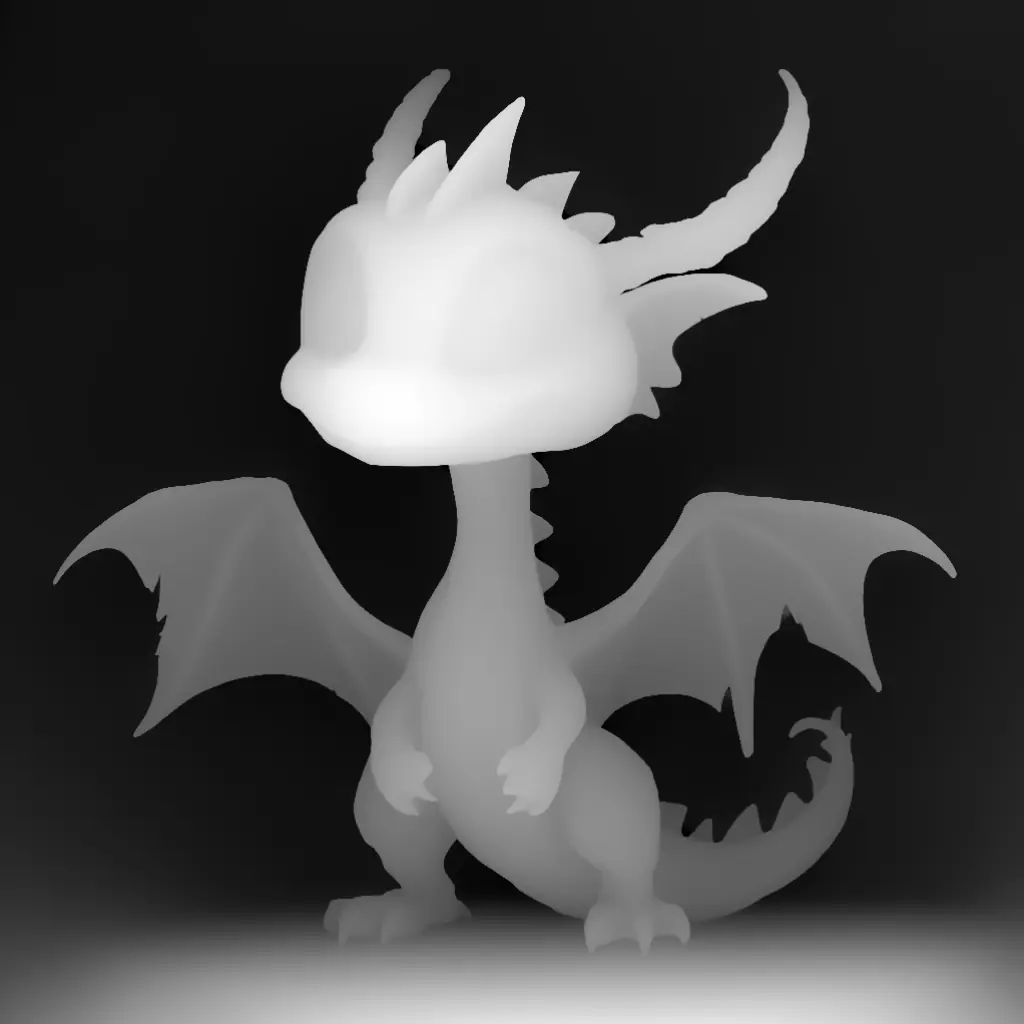
This workflow teaches you how to guide Stable Diffusion 3.5 with a depth map so your generations respect the structure and perspective of a reference image. It loads the SD 3.5 Large checkpoint (sd3.5_large_fp8_scaled.safetensors) with CheckpointLoaderSimple and a high‑quality VAE (vae-ft-mse-840000-ema-pruned.safetensors). Your text prompt is encoded by CLIPTextEncode, and KSampler handles diffusion using a latent canvas defined by EmptySD3LatentImage, so you can set an exact output size. VAEDecode, PreviewImage, and SaveImage complete the loop so you can inspect and export results.
Depth guidance is provided through ControlNet. ControlNetLoader loads sd3.5_large_controlnet_depth.safetensors and ControlNetApplyAdvanced attaches the depth conditioning to your prompt with adjustable strength and start/end percentage. The reference image comes in via LoadImage, is optionally resized with ImageScaleToTotalPixels, and then converted to a depth map by the included depth preprocessor node (the custom node identified by 6b0ed7ac-f476-44c9-9dad-b3f23ef985f8) using the lotus-depth-d-v1-1.safetensors model. For image-to-image variants, VAEEncode can seed KSampler with the reference image latents; for pure text-to-image with depth guidance, use EmptySD3LatentImage. ConditioningZeroOut is available if you want an empty negative prompt. This combination makes it easy to preserve scene layout while freely changing style, lighting, and details with your prompt.
API
Use this workflow from code
Every Comfy workflow is a JSON graph. The payload below is this workflow, exactly as ComfyUI runs it — fetch it from the URL, keep it in version control, or load it in ComfyUI and run it node by node.
GET https://comfy.org/workflows/download/45a8be9c1124.jsonFetching workflow JSON…
Run it from Python or TypeScript with the Comfy SDK. The same code targets Comfy Cloud or a ComfyUI you host yourself — only the base URL changes.
# Install (beta)
pip install comfy-sdk        # Python
npm i @comfyorg/sdk          # TypeScript

# Run "SD3.5 Large Depth" (Python)
from comfy_sdk import Comfy

client = Comfy(api_key="comfyui-...")

# This workflow, exported in API format (see note below)
wf = client.workflows.from_file("sd3.5_large_depth_api.json")

asset = client.assets.from_file("input.png")
wf.set_input("45", "image", asset)  # LoadImage

wf.set_input("57", "text", "your prompt here")  # CLIPTextEncode

job = client.run(wf)
for output in job.get_outputs("9"):  # SaveImage
    output.to_file(output.name)
The SDK takes a workflow in API format: open this workflow in ComfyUI and use File → Export Workflow (API). API access requires a Comfy Cloud plan with an API key. SDK docs · Get an API key
FAQ