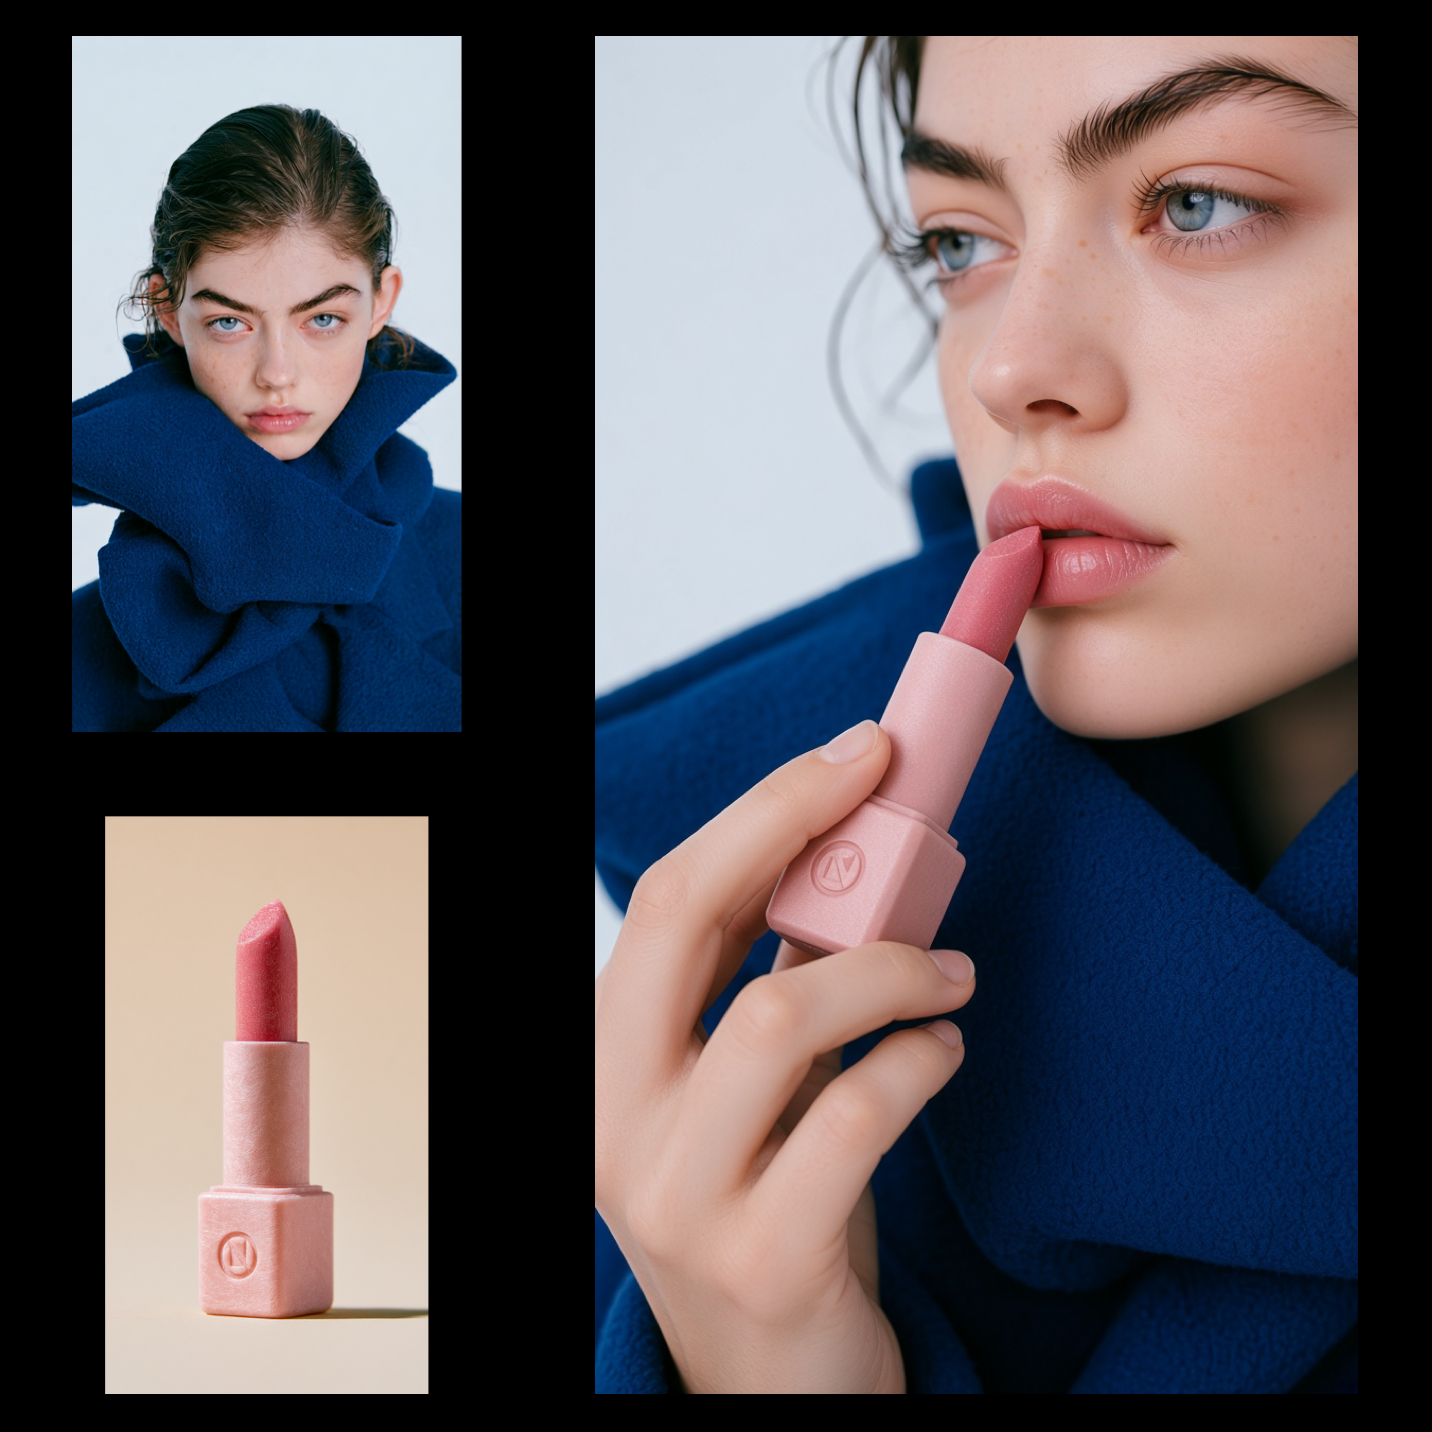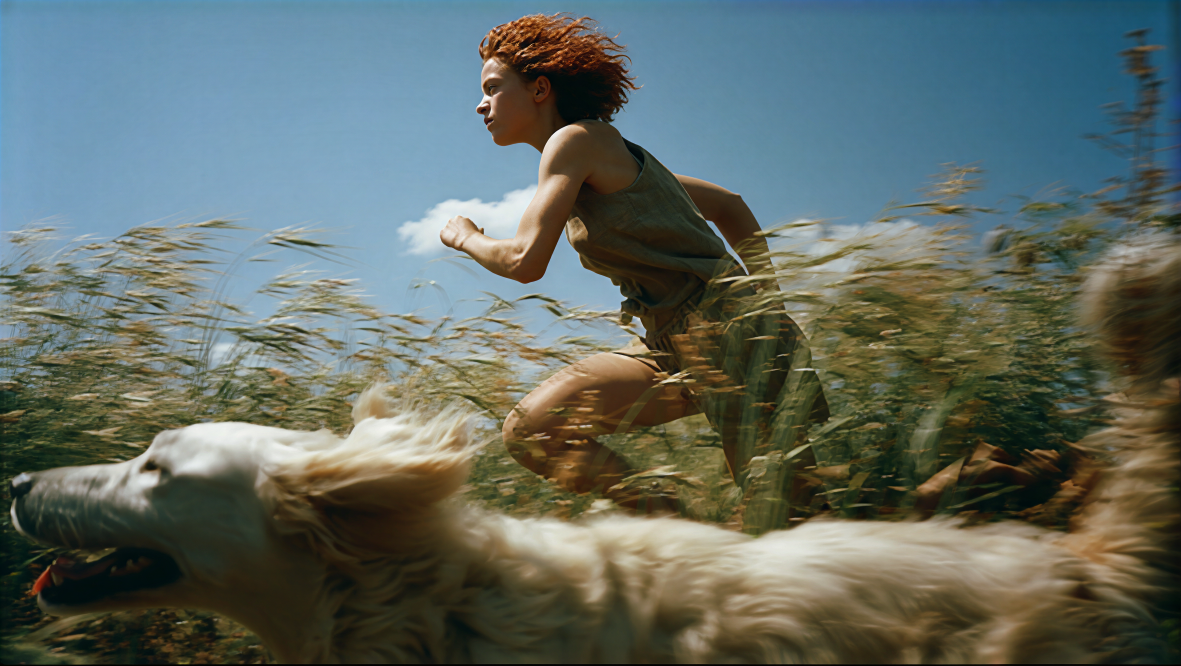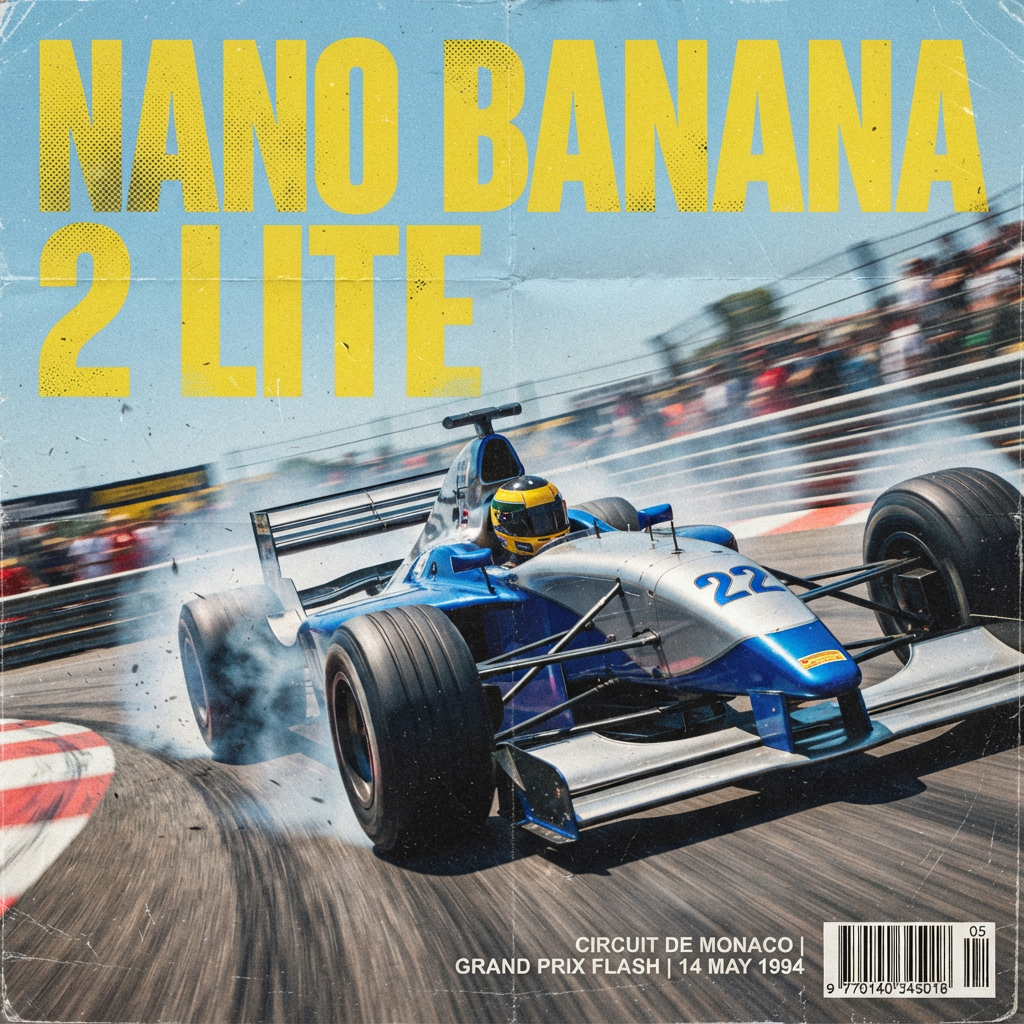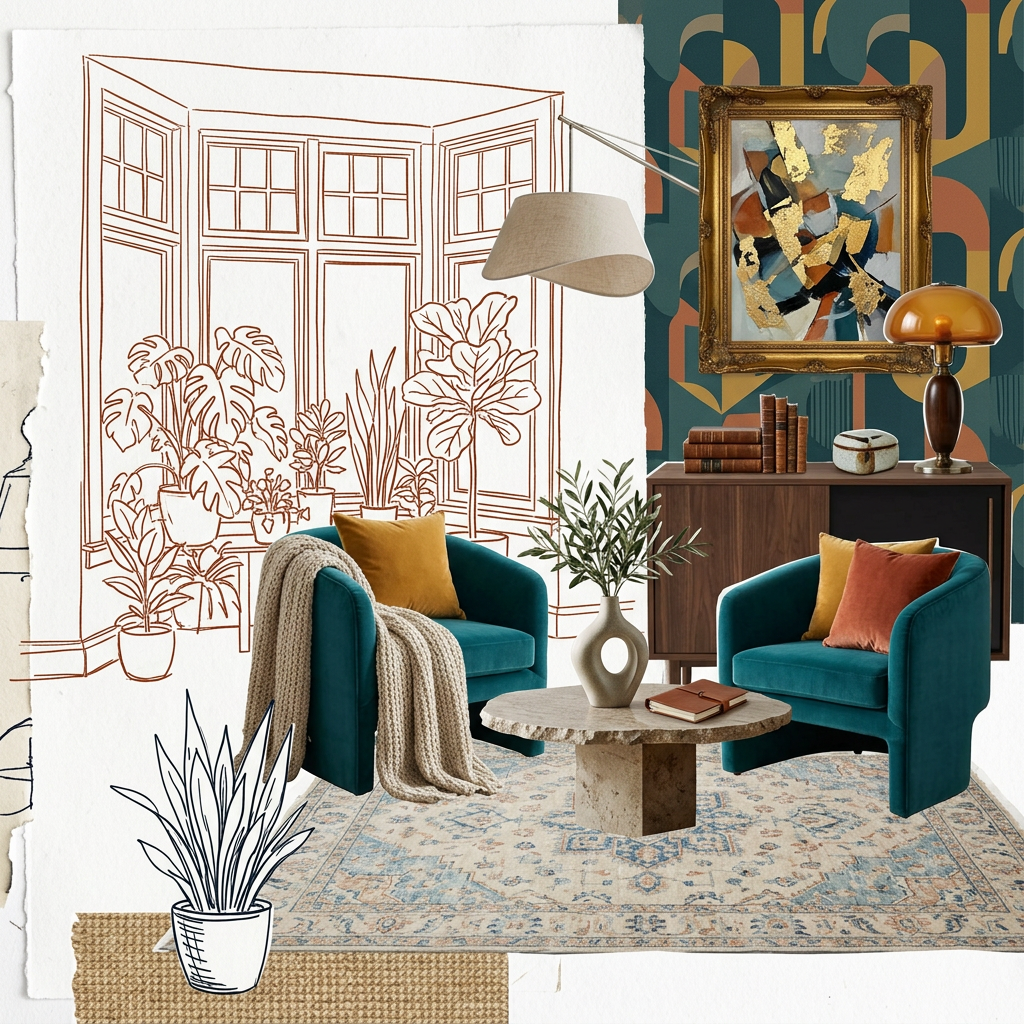
This ComfyUI workflow generates images from text using Flux.1 Schnell (full) with a minimal, fast sampling setup. It combines DualCLIPLoader to load both CLIP-L and T5XXL text encoders, CLIPTextEncodeFlux to turn your prompts into Flux-ready conditioning, and UNETLoader to load the flux1-schnell.safetensors diffusion model. EmptySD3LatentImage defines the latent canvas size and batch, KSampler performs denoising in as few as four steps, and VAELoader + VAEDecode reconstruct the final image for SaveImage to write to disk. A ConditioningZeroOut node provides an unconditional branch for classifier-free guidance when you’re not using a negative prompt. MarkdownNote nodes in the canvas clarify what to do at each stage.
Technically, the workflow follows a standard latent diffusion path adapted for Flux/SD3-style latents: initialize an EmptySD3LatentImage, encode text with CLIPTextEncodeFlux, run the UNet through KSampler with a low step-count tuned for the Schnell variant, then decode with the selected VAE. The “Step 1 - Load Models Here” group centralizes model selection: flux1-schnell in UNETLoader, CLIP-L + T5XXL in DualCLIPLoader, and a compatible VAE in VAELoader. “Step 2 - Image Size” sets your width/height and batch, and “Step 3 - Prompt” handles positive/negative prompts. The result is a fast, 4-step text-to-image pipeline that balances speed and quality under the permissive Apache-2.0 license for the Flux.1 Schnell weights.
API
Use this workflow from code
Every Comfy workflow is a JSON graph. The payload below is this workflow, exactly as ComfyUI runs it — fetch it from the URL, keep it in version control, or load it in ComfyUI and run it node by node.
GET https://comfy.org/workflows/download/9cc2917611e9.jsonFetching workflow JSON…
Run it from Python or TypeScript with the Comfy SDK. The same code targets Comfy Cloud or a ComfyUI you host yourself — only the base URL changes.
# Install (beta)
pip install comfy-sdk        # Python
npm i @comfyorg/sdk          # TypeScript

# Run "Flux.1 Schnell Full: Text to Image" (Python)
from comfy_sdk import Comfy

client = Comfy(api_key="comfyui-...")

# This workflow, exported in API format (see note below)
wf = client.workflows.from_file("flux_schnell_full_text_to_image_api.json")

wf.set_input("41", "text", "your prompt here")  # CLIPTextEncode

job = client.run(wf)
for output in job.get_outputs("9"):  # SaveImage
    output.to_file(output.name)
The SDK takes a workflow in API format: open this workflow in ComfyUI and use File → Export Workflow (API). API access requires a Comfy Cloud plan with an API key. SDK docs · Get an API key
FAQ